The Presales Assistant Reads the Site You Read
An answer written on the website should be one the assistant can find.
The presales assistant on the website now draws its knowledge from the public pages each site build publishes, in Chinese and English, including page-only content such as FAQs and AI client setup steps. A new snapshot replaces the old one only after every document has been written and read back; if a run fails, the previous one stays in use.
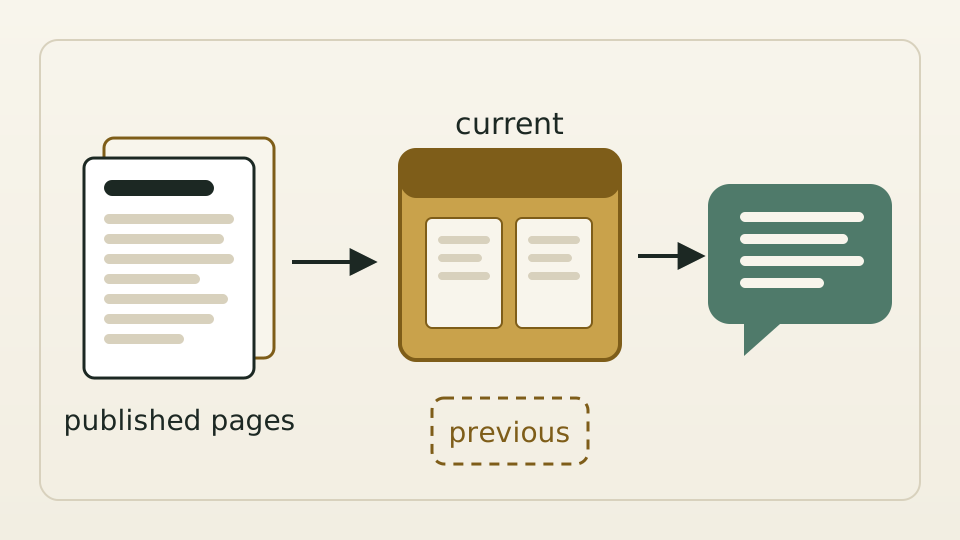
A visitor wants to connect their usual AI client and asks the presales assistant on the website how to do it. The setup steps are on the website’s pages, but the assistant’s knowledge used to come from a separate product data export that covered product descriptions only: FAQs and setup instructions written on the pages never reached it, and retrieval returned short abstracts.
So we stopped maintaining a copy for the assistant. Every site build already renders the full body of each public page. Presales knowledge is now extracted from those rendered pages in Chinese and English, keeping the tail of long pages as bounded chunks linked to their source. Each snapshot of the assistant’s knowledge is generated from the pages published at the time.
The sync tool validates the whole export, writes every document and reads it back, and only then points “current” at the new snapshot. If a run fails, the assistant keeps the previous one; if nothing changed, nothing is written. When answering, retrieval stays inside the current snapshot and the visitor’s language, and reads the page text itself rather than a summary.
The scope has clear edges. Only public, indexable pages count; scripts and page chrome are stripped, and a page with a missing body fails the export. Content from older exports, including the former tail of a page that has since been shortened, stays out of the current snapshot. Individual daily stories are not included, while the story index is.